Inside Descant

Results, product updates and lessons from engineering with Descant.

Contents · 12 posts
Engineering3 min readBy Tim Layton

My hypocrisy about AI coding

Unstructured AI coding left me disconnected from the work. I now delegate more implementation than ever, and I've never enjoyed being an engineer more.

There’s an obvious hypocrisy in what I’m about to say. Writing code through unstructured prompting left me disconnected from the work in a way that felt bad. I disliked it much more than crafting code by hand.

We were trying to build multiple ambitious projects at once, and I built tooling to make that possible. I hadn’t intended the tooling to become a product, but it did.

I’m having AI write more of the code, with less of my involvement in the implementation, and somehow I’ve never enjoyed being an engineer more. From the perspective of how much code I’m personally writing, pointing out the hypocrisy is entirely fair. I’m doing more of the thing I’m saying felt wrong.

But the part that changed for me was how much thinking I was doing, what I was thinking about, and what happened to that thinking once implementation started.

With unstructured prompting, I spent a lot of time steering a session, discovering what it had misunderstood, reconstructing context, and asking it to try again. I was deeply involved, but much of that involvement was cleanup. Producing more code faster had given me more code to inspect without necessarily giving me a better understanding of the solution.

Now I spend more time on system architecture, technical designs, and applying design patterns across larger bodies of work. I can think through where responsibilities belong, how changes fit together, which dependencies we can eliminate, and whether we need to build something at all. I get to refine the solution before there are thousands of lines of implementation making the first plausible approach expensive to reconsider.

That feels much closer to the kind of laziness I’ve always considered a virtue: putting more thought into how to do less work while still solving the whole problem.

The implementation matters just as much. I’m handing that design to a structured, type-driven engineering process that carries requirements through the work and checks evidence against them. It investigates the surrounding system, considers the problem from different perspectives, works through a plan, and subjects the implementation to verification and independent review. The thinking has somewhere to go, and there is machinery to check what happened to it using a system I trust.

That’s a very different thing from giving a model a narrow prompt, setting the thinking effort to “ultra,” and accepting its account of how thoroughly it solved the problem (✋ guilty). The model can put considerable effort into the problem it was given and still miss that the problem was framed too narrowly. And a confident explanation of what it checked still leaves you needing evidence that those checks establish what matters.

I still care about the implementation, and I still want to refine it, but through iterating on an autonomous engineering system so I can scale the refinement. I've hardly become indifferent to the code because something else writes it and still feel a very strong pull to make sure the code it’s writing is something I'm happy with. What changed is that I can put more of my effort into understanding and designing the whole solution, with a process that carries that care into the implementation and the personal benefit of knowing that I'm committed to making that process better every day.

You can still call that hypocrisy, I wouldn't disagree. But to me, it feels like getting back to the virtue of laziness that made it useful in the first place: doing less because you thought more, while still getting the job completely done. And doing real [strategic] engineering again, not babysitting.

Engineering15 min readBy Tim Layton, founder of Autonomy

Why I built Descant

The problems that became Descant, what running it taught us, and why I enjoy engineering more than ever.

I left Boulevard last year in November without a real plan, but we had a project in flight we thought had potential: TriviaPot, real-time live trivia matches playing to win cash. You pay an entry fee, there is a pot based on the size of the game, the winner takes all, and a percentage of the pot goes to us as a platform fee.

We built out a fully working web app version for testing, with no real money. Games had bots in them to fill out the games, and with all the trivia AI-generated, it was unlimited. You could do custom games as well and get trivia on Mario Kart or knitting or technical terms for NSFW words or the wonderful world of hardwood floors—literally whatever. It would generate trivia based on a rubric, score it, and validate it with a different model. It had some software checks in there, too, to make sure the answer didn't end up in the question or hint and to check the overall rubric score. Multiple models needed to validate the correctness of the answer, which software checked to be sure it was all passes—that kind of thing. The trivia would pass or get thrown away.

We sent it out for testing and had some positive feedback, but not enough sticky engagement, and plenty of things that we could change. Satisfying the legal and compliance requirements for the real cash gaming aspect was a capital and resource investment that didn't seem worth it for a game that, by itself, just didn't seem fun enough to come back and play. Instead of ditching the project entirely, we continued to work on it on the side, completely revamping the gameplay to layer in multiple in-game currencies, an in-game currency store for buying upgrades, power-ups, multipliers, reactions, daily quests for bonus currencies, multiple-choice answers (you used to type the answer), and all players funneling into one matchmaking system. The idea was to see if we could make a game that was good enough to draw in players without the real money aspect, build it native, get it in the app store, and, if we got traction, decide if the traction was worth the further resource commitment to pursue a real money gaming version.

Meanwhile, with the rapid advancements in AI and agentic coding, we wanted to test a hypothesis that was now only possible given the speed at which we could build out MVPs: if someone, a business or person, has a real painful problem worse than just an inconvenience and we build a product that solves their problem, there are enough people with the same problem to sustain a profitable business, even if not a significant bottom line. The new speed to MVP significantly reduced the risk and would make it a repeatable pattern. It would look more like a large portfolio of micro-niche products that collectively would generate significant net revenues, with a chance of discovering a problem a lot of people have that then becomes the primary focus.

We still couldn't build fast enough to really test this hypothesis. The AI slop code, prompt-only coding (e.g. vibe coding), and how necessary it was to still be deeply in the loop on the work prevented this from being a reality. There are a lot of people out there who disagree, and I will confidently tell you I think they are wrong. People with no software engineering experience don't know what they are missing, and that by itself is tremendously dangerous. People who are skilled software engineers do know there is still a lot to build, even for an MVP to be safe and stable enough. If you still are like, “Hey, we got this up in 5 days and it's fully production-ready,” your idea wasn't that ambitious. That's not a knock; it's smart to start small and make sure what you build is solid. But for the problems we were trying to solve, the small unit, the MVP, was still big. We are testing a hypothesis in which I don't come up with any ideas.

To support the level of ambition we had, I started developing a lot of custom tooling around developing code with AI, the first part starting with how to solve the quality problem—like really solve it. Depending on someone's nature and recent experience, they might say that the frontier models are already good enough, and I disagree, not on opinion but proof. Very good, yes; consistent staff+ level quality, not even close, not even remotely close. I needed excellent every time, over thousands and thousands of pull requests.

Once quality was in a good spot, we needed to solve all of the other complexity that comes with operations and dynamic manufacturing lines: assembling complex components together in the right order, sometimes with a sprawling dependency graph, over long horizons of long horizons that adjust to variability, where the edges don't crumble and big gaps aren't left behind. Most important, it needed to be safe, trusted software. Not just because we needed to rely on it, but because our customers relied on us, even if starting with only one customer per product. MA2H, OH HAI, and Issuegraph were all born out of this very difficult problem to solve for coordination and communication in ever-changing complex environments at scale, in a way that's so reliable that trust becomes automatic.

When it all came together and was working relatively smoothly, I was excited to show my friend, who simply said, “Well, that's your product.” That immediately felt like the most obvious thing that just didn't occur to me. That version became Descant's first prototype, which shipped over 20K PRs in a matter of months (not joking, look at my GitHub contributions) before we had the production version fully built.

So we had mountains of data with over 100 million tool calls and full transcripts. We knew very precisely where mistakes were made, what tools mattered, what didn't, where tokens were spent and had little to no impact, and where work degraded when running autonomously for weeks. We saw cruft build up, tech debt emerge, how gaps formed, where models made repeated mistakes, and the correlated data between prompts given and actions [not] taken. We saw where and what prompts could be trusted more than others (spoiler alert: never trust prompts; prompts are not contracts—they are seeds, more on this later). We had a roadmap for how to improve and often eliminate these problems. The result is something that is still pretty mind-blowing to me when I use it now.

An early benchmark on SWE-bench Pro scored 86.46%, where the underlying models being used (Descant, as of now, uses multiple models—also more on this later) collectively scored a 62%. At the time, the top spot was held by Mythos 5 with an 80.3%. I was shocked and excited, probably too excited, because Descant wasn't designed to optimize for single-model quality, and I started making the story about the bench score.

Descant's quality is designed around a consistently high bar that can be trusted autonomously over thousands of issues or more. Descant genuinely improves in a way that is measured and repeatedly tested and optimized, and is a meaningfully positive steward of the project—leaving code better than it finds it. This happens through follow-ups to keep scope tight, which Descant will then automatically pick up and run through a new pipeline in parallel if possible, but often serialized with the existing work to avoid conflicts and rebases. Those are one of the biggest sources of waste and something thoughtful coordination can eliminate, not just with Descant but with people teams, too. Descant also grooms issues related to the work and its edges that might have been impacted, and keeps learnings up to date, not letting a once-useful document become stale and a faulty direction for future engineering, whether by Descant or a person.

Descant is designed around professional work. It brings the best version of itself every time, and that consistent high quality is what establishes the trust and makes full autonomy possible. It just so happens that if the best a single model can bring is a B some of the time, Descant will end up bringing a B+ or an A because of what we've learned around error de-correlation and getting models to think differently to avoid repeating the same mistakes. And it will bring that B+ or A every time. To be clear, I am not a researcher—we've simply backed into the relevant research and its understanding by iterating over this process now over 250,000 times. Fun fact: the name Descant is an acronym of different methods that inspired its design or are applied to Descant directly.

While I think the benchmark scores are actually more harmful than helpful to Descant, I still publish the score because there needs to be at least one succinct, quantified way to express the capability/quality of at least one of the multiple dimensions of Descant, like the most recent 82.3% on DeepSWE v1.1. This is just for you to stick around to read more or reach out to have a conversation. I never want someone to make a commitment to Descant on a bench score alone. It's just one signal. You should get to truly see and experience the quality. This is something we need to figure out and are always working on or thinking about. Currently, there is no benchmark designed to truly test what Descant is uniquely capable of, and it's hard for us to create our own benchmark that no one else runs and be the only one that is good at it. It's like playing Monopoly with a little kid who you let make the rules.

I've never enjoyed being an engineer more than I do now, specifically with Descant. Compare that with writing code through unstructured prompting alone: that was the opposite for me. I disliked it much more than crafting code by hand. Handcrafting code and perfecting it line by line, to me, feels like what Japanese woodworking, specifically Kigumi (木組み), looks like. That kind of care over the work and, on the Japanese theme, Takumi (匠) and a lifelong dedication to the craft is something I enjoy very much (not putting myself on the same level as a master takumi, just saying I enjoy the dedication to constantly improving and crafting code).

Unstructured prompting is the opposite. It's sloppy, loses the detailed refinement, and, even though it produces a lot more code faster, leaves me disconnected from the code in a way that just feels bad. Objectively, it seems wrong, too. Some of my closest friends and former colleagues, whom I would put on the level of a takumi master, are disciplined about their craft. For them, unstructured prompt coding isn't necessarily a massive boon in productivity. There is more time cleaning up than crafting. And it matters when they are building some of the most heavily used software and infrastructure in the world. Single lines can matter a lot there. Even well before AI coding, there was no shortage of stories where single lines resulted in significant platform and internet outages.

With Descant, the thing that I know, and that hopefully many people and teams will experience and come to appreciate, is the level of effort that has gone into bringing craft and discipline to what Descant creates for you. Complete thinking for the problem space; specific areas of research we know from our data correlate to better outcomes; thoughtful and precise planning; additional focus on areas we know are consistent problems, like integration seams; behavior-in-essence red-first checks at those boundaries (think BDD at integration points, but the tests live in the unit-test framework); the acceptance criteria and requirements enforcement; maintaining strict execution ordering through Issuegraph (born out of necessity); structured review that is verified, with every change looking to reduce complexity—complexity we quantify and verify. And that's not all of it.

The precision that I know is there makes me love building with Descant, because the precision isn't just a prompt. Yes, we use prompts and carry that precision through as schema-validated data, and that's enforced in execution or used to verify model assertions. There are efforts in every permutation and at every level to act with professional engineering discipline, to craft the outcome. I can name more things, but I won't because it's a lot and, yes, it all matters. The data showed us what resulted in consistent quality or improvements in the outcome. When thinking about smaller units of work, the parts of the system that right-size the effort are particularly helpful when it comes to cost. A quick helper function does not need all of the things.

And it can be done at scale. That's why I love it—the impact, while still building with a system that enforces professional, disciplined engineering that upholds craft pragmatically, instead of my time being consumed by unstructured, inconsistent prompting and results in what felt like a forced attempt to be more productive. You might find that hypocritical, and I wouldn't disagree with you. I'm talking about my care and enjoyment in crafting code, yet having Descant handle the implementation fully autonomously. That's pretty close to a perfect example of hypocrisy. But I see it a different way.

I am getting back to crafting and doing it at a higher level. Refining system architecture, subsystem designs, iterating on technical design, and exploring design patterns and applying the best fit for the use case feel like my new version of writing crafted lines of code. I can apply creativity more than I've ever been able to in software engineering. It's such a bigger playing field with so many more possibilities that can be met with engineering that scales and a level of quality I feel good about—because Descant is crafting.

You might feel differently because the code is not perfection, but Descant isn't claiming to be a master crafter. Many of us who have been coding our entire careers, maybe even since we were kids, and have never stopped working to improve still don't call ourselves a master crafter and probably never will. I certainly don't and won't. Descant isn't either, especially because it's just getting started. We are just getting started. And we are dedicated to Descant's craft, constantly testing and looking at data both manually and automatically to inform continuous improvement.

Designing purely at the architecture, systems, and patterns level and delegating implementation to a fully autonomous system is a different way of working. For me, the leap from handwriting code to prompt-driven development was much smaller than the leap from prompt-driven engineering to fully autonomous implementation. And it's been one of the greatest joys for me as an engineer. I hope it is for you and your teams, too.

Descant is largely thought of as a harness, and it is, partly. I see it as only 1/3 harness, with the harness being, as of the current moment in time, simultaneously the most critical and the least valuable part. As models continue to improve, less and less of the harness will be needed. And the sooner we can get rid of that part, the better, because it limits what is possible with Descant, like building backwards compatibility for the things the model can't yet do for itself.

The other two parts are structure (shape, tools, operations, information, instruction, purpose, process, levers, capabilities...structural things) and the output shape. These have nothing to do with model intelligence; they are complementary to intelligence. In fact, intelligence can't do anything without them. That seems weird to say because when we think of model intelligence, we think of models with many of the structural components, not without them. Just like we don't think about what a carpenter can't do without their tools—in sticking with the woodworking references.

More advanced models will be able to start instantly creating many of these structural components based on the ask. What's left are things like information, instruction, and purpose, which are really all different types of information. No matter how intelligent models become, even like ASI level and whatever comes after that, intelligence cannot replace missing information. It can research, investigate, and synthesize information, but it cannot create missing information. With instruction and purpose as types of information, they are critical components.

Descant already has a lot of these components. We continue to improve them, and they are directly responsible for Descant's delivery of consistent, high-quality results. This is the part of the system that enables scaling and the ability to do a 1-year migration in a weekend, which still requires a well-crafted technical design to break down dependencies and allow for the kind of concurrency needed (think hundreds to thousands of PRs at a time every 2 hours).

The third part is the output shape, which, put plainly, is the impact potential. Descant's potential impact is limited by the need for a substantial harness, which is mostly focused on raising the floor and elevating the models. Descant's full potential will start to be realized when we can focus that energy and dedication on raising the ceiling and continuously push the limits of next-generation models.

Milestone4 min read

Descant scores 82.3% on DeepSWE v1.1

What resolving 93 of 113 tasks tells us about autonomous software engineering—and what it leaves unmeasured about evolving a codebase over time.

Descant is a fully autonomous software engineering system built to advance and maintain substantial codebases: paying down technical debt, accelerating feature development, and carrying large refactors through to completion. It coordinates work across thousands of interconnected issues, learns from each run, and carries that knowledge forward as the codebase evolves over months and years. For new products, Descant can start from a single issue, a PRD, a technical design, or a backlog you’ve already structured—giving you control over how much is defined up front. It decomposes the remaining work into implementation issues, maintains their dependency graph, and carries them through to a working product.

We chose DeepSWE v1.1 because its original, long-horizon engineering tasks closely match an important part of that work. It tests whether a system can understand a codebase and implement a substantial change. The longer horizon—learning from previous work, coordinating dependencies, and carrying a product forward through thousands of changes—extends beyond what a single-task benchmark measures.

Descant · Soprano 782.3%
Muse Wonder79.0%
Gemini 4 Argon77.9%
GPT-6.1 Sol75.2%
Claude Opus 5.574.2%
GPT-6 Astra74.1%
Grok 4.771.0%
Claude Fable 570.0%
0%50%100%

Source: llm-stats.com DeepSWE v1.1, as of October 14, 2026.

Descant resolved 93 of 113 tasks, scoring 82.3% on DeepSWE v1.1. The graphic above places Descant’s system-level result alongside the benchmark’s published frontier model scores.

Engineering across the life of a codebase

Descant decomposes complex requests into actionable issues, builds their dependency graph, and coordinates implementation and review. That work led us to create issuegraph, an open specification for expressing the relationships between issues.

As changes land, Descant reassesses the work around them. It closes issues already resolved by other changes, updates those whose requirements have shifted, and repurposes work that remains useful. It records learnings from each run and can draw on them in subsequent runs, carrying knowledge forward as the codebase evolves.

The system is designed to coordinate 1,000 concurrent runs and beyond, with dependencies determining which work can proceed together.

We have used Descant to refactor and evolve TriviaPot across thousands of issues, and to take OH HAI from a single issue to an operational product. Those projects exercise the continuity that isolated benchmark tasks leave unmeasured: each change becomes part of the environment in which the next decision is made.

Why DeepSWE

DeepSWE’s tasks and reference solutions are newly authored against existing codebases. They span TypeScript, Go, Python, JavaScript, and Rust, with purpose-written verifiers that evaluate the requested behavior. This makes it a useful test of solving unfamiliar engineering problems. DeepSWE’s methodology explains how that construction differs from benchmarks assembled from existing fixes.

We originally evaluated Descant on SWE-bench Pro, scoring 86.6%, with later runs approaching near-perfect scores. Published audits also identified weaknesses that could inflate results: insufficient test coverage allowed incomplete solutions to pass, and reference fixes accessible through repository history could be recovered rather than independently developed. DeepSWE’s original tasks and purpose-written verifiers offered a stronger basis for measuring how Descant handles unfamiliar, challenging engineering work.

FrontierSWE measures exceptionally difficult engineering and research work, including systems implementation, performance optimization, and scientific computing. It explores the technical capabilities of the frontier models Descant brings together. For this evaluation, we wanted to measure how effectively Descant combines those capabilities to deliver challenging, long-horizon engineering work in existing codebases. DeepSWE’s mix of substantial changes across varied projects was the closer fit for the work teams would entrust to Descant.

Broader agent benchmarks such as Terminal-Bench can measure useful component capabilities. They don’t establish whether a system can manage the continuing evolution of a software product. None of these scores, including ours, answers that larger question on its own.

What the results taught us

Reviewing the results surfaced omissions and contradictions between issue descriptions and hidden tests: an unstated name or value, or a test expecting behavior different from what the issue described.

Ambiguity is also part of real software engineering. Descant reasons through it using the requirements and evidence available in the repository. When two plausible interpretations can coexist cleanly, it can implement a solution that supports both, preserving valid behavior without making an unsupported choice.

When the alternatives are mutually exclusive, multiple models collaborate to examine the direct evidence and determine the most defensible direction. The reasoning effort is matched to the problem: a narrow uncertainty should not require the same deliberation as an architectural decision.

Our review also identified cases where Descant made a defensible engineering choice that the hidden tests rejected. Some tests required behavior the issue never specified or contradicted what it requested. In other cases, Descant deliberately departed from a stated requirement to preserve correctness or protect existing data, explaining that choice in the pull request.

Those tasks remain failures in the reported score. We stand behind choices where the evidence supports the engineering reasoning. Benchmarks provide useful evidence, but the outcome that matters is reliable software that evolves with your business and delivers value to your customers.

All 113 benchmark task repos and the solutions are published. If you’d like to dig into the code, PRs, and task notes, access is available on request.

Product update2 min read

Over 1,000 beta signups. Here’s what comes next

Closed beta is approaching. An update on who Descant is for, agent-native access, and the capability, trust, and scale we have been bringing together since June.

Bringing together capability, trust, and scale
Bringing together capability, trust, and scaleYou and your agent come in through the same door with the same permissions, and your authority over scope, priorities, approvals and spend sits at that door. Inside, the work runs within nested boundaries: capability approvals, scoped credentials, and a sandbox for isolated execution. In the sandbox the work fans out into five colored lines and converges again. An outbound line stops at the sandbox wall: there is no route out. A narrow gap reaches only designated services. The finished work leaves through review as a pull request. Faint copies of the whole pipeline stack behind it, one per run.YouWEB APPYour agentCLI · MCPYOUR AUTHORITYscope · priorities · approvals · spendCAPABILITY APPROVALSSCOPED CREDENTIALSSANDBOXISOLATEDEXECUTIONthe workNO ROUTEDesignated servicesRESTRICTEDEGRESSREVIEWPull request

Thank you. Here is where we are

Over 1,000 signups have joined Descant’s beta list. Our promotion so far has been one public announcement post, with no paid acquisition. To everyone who signed up, shared the work, or followed along: thank you.

Since that June announcement, we have been hardening Descant for closed beta. The next generation is being developed through work on TriviaPot, OH HAI, and Descant itself. Our September 11 post explains the engineering framework; this update is about making that capability ready for the people who will use it.

Start with a repository and one issue or ten thousand

Descant is for software companies carrying substantial technical debt, engineering teams accelerating delivery, maintainers short on bandwidth, solo developers shipping products, and founders building with AI. You can start with a GitHub repository and a single issue, or a backlog of ten thousand.

If you build by describing what you want to an AI agent, Descant is for you too. Production-grade software needs more than a working feature: tests and CI, security, observability, resilience, and scalability. Descant brings disciplined engineering to foundations you may not yet know to ask for.

Our CLI and MCP interfaces give agents access to the same underlying capabilities and permissions as the human interface. An agent can help prepare your repository and issues and work with Descant on your behalf. You retain authority over scope, priorities, approvals, and spending.

Bringing capability, trust, and scale together

We have been refining the tools agents need alongside the boundaries that govern their use. Capability approvals define permitted operations; isolated execution, restricted egress, scoped credentials, and review provide separate layers of protection.

The execution sandbox network has no general internet route and permits access only to designated supporting services. A malicious or misinterpreted instruction in an issue or repository cannot create an outbound route that the environment does not provide.

We are designing infrastructure to fit workloads ranging from one issue to multiple multi-gigabyte repositories and backlogs of hundreds of thousands of issues. Execution capacity and concurrency can grow when thousands of independent tasks are ready, governed by dependencies, shared-code constraints, and your budget.

Closed beta is approaching. The work now is bringing these capabilities together into a dependable product that meets professional, production-grade standards. Think about the first outcome you would entrust to Descant: one issue to finish, a product to build, a backlog to resolve, or a codebase to transform.

Engineering3 min read

What fully autonomous software engineering requires

Fully autonomous software engineering is the North Star. Carrying a real codebase forward through changing requirements, learning, and repeated convergence is a necessary step toward it.

Fully autonomous software engineering is the goal

Descant’s North Star is fully autonomous software engineering: a system that can carry an engineering goal through implementation, review, integration, and maintenance, with people setting direction and retaining authority over its boundaries.

Sustained engineering across an entire codebase is a necessary capability on that path. Real software evolves over weeks, months, and years. Requirements change, technical debt accumulates, and each completed change alters the work still to come. The system has to preserve architectural intent while adapting to what it discovers.

Completing one difficult coding task demonstrates a useful capability. Carrying a codebase through thousands of coordinated changes requires continuity: the ability to decompose goals, relate work, implement and review, groom and learn, and repeatedly converge as the product changes. That lifecycle is the framework we are building into Descant.

Turn a goal into coordinated work

Descant assesses whether an eligible issue is too large for a focused pull request. Oversized work is decomposed into smaller issues with explicit scope and relationships. A single product brief can grow into hundreds or thousands of issues as requirements are broken down and implementation reveals missing pieces. Small pull requests keep that effort incremental and reviewable.

Issuegraph frontmatter and labels make the plan machine-readable: where work was decomposed from, what belongs together, what must be serialized, and what is blocked by a dependency. These relationships let the system coordinate changes without losing their connection to the original goal.

Implementation and separate review operate within the current issue’s scope. Tangential fixes, technical debt, and out-of-scope improvements become follow-up issues. Leaving the codebase better includes preserving those discoveries so they can be prioritized and addressed.

The same discipline matters in an established enterprise system. A large technical-debt backlog needs careful sequencing and architectural continuity. Replacing a shared contract, migrating its callers, and retiring the old implementation are related changes whose order matters. Sustained engineering carries that sequence through while keeping each individual change focused.

Learn, reconcile, and converge again

Every completed change affects the surrounding backlog. Related issues may need updated context, narrower scope, a new dependency, repurposing, or closure because their work is already satisfied. Grooming reconciles those issues and records relationships at the edges as they become apparent.

Documented learnings carry architectural decisions, repository conventions, and resolved review findings forward. Incremental compression and relevance updates keep that knowledge useful as the codebase evolves. Analysis of pipeline runs also surfaces opportunities to improve quality, cost, and efficiency. Each run should leave the next one better informed.

The result is repeated convergence. Discovering necessary work can expand the backlog before implementation catches up. As related changes land and residual work is resolved, the system converges on a working product. New requirements begin another cycle, with the existing code and accumulated knowledge as its foundation.

We develop the next generation of Descant through this process on TriviaPot, OH HAI, and Descant itself. TriviaPot reached a working product through an in-place rebuild, then went through a deliberate design overhaul. OH HAI grew from a small set of product-level issues into an application, service, CLI, and agent integrations.

That is why sustained engineering matters to the larger goal. Fully autonomous software engineering requires a system that can keep bringing real work to completion as the codebase changes. Our focus on convergence is bringing that system closer to closed beta.

Case study2 min read

Rebuilding TriviaPot in place, all the way to the App Store

An existing codebase, weeks of sustained engineering, and the thousands of issues behind a finished product.

TriviaPot

The work behind the product

TriviaPot · April–September 2026

2,665

created

2,497

closed

TriviaPot issue creation and closure over timeCumulative issues created and closed. The gap between the lines represents outstanding work in this reconstruction. Numbered markers trace expanding work, completion catching up, a working product, and the optional design overhaul. Counts include the repository's earlier issues; they are not counts of shipped features.01k2k3k1234AprMayJunJulAugSep
Issues createdIssues closed
  1. May

    The work expands

    Descant decomposes the rebuild and discovers follow-ups. Issue creation initially outpaces completion.

  2. Early June

    Completion catches up

    The backlog reaches its widest gap. Completion then outpaces new issue creation as implementation converges.

  3. Late June / early July

    A working product

    The initial implementation converges. TriviaPot is working well, with the core feature set in place.

  4. Early July

    A deliberate design overhaul

    We choose a full visual redesign and remove real-money features for the free-to-play release. This new scope creates the next wave of issues.

Repository-wide GitHub issues through September 3. Reconstructed from creation and latest closure dates, retrieved September 12; intermediate reopenings are not shown. Closed includes completed and retired issues. Pull requests are excluded.
View chart data
Weekly cumulative TriviaPot issue counts
DateCreatedClosed
2026-04-01189169
2026-04-08189169
2026-04-15191191
2026-04-22191191
2026-04-29192191
2026-05-06193191
2026-05-13629308
2026-05-201235862
2026-05-2715871010
2026-06-0321091379
2026-06-1021331535
2026-06-1722081855
2026-06-2422251976
2026-07-0122412068
2026-07-0825242404
2026-07-1525612457
2026-07-2225612457
2026-07-2925612457
2026-08-0525612457
2026-08-1225892473
2026-08-1926272487
2026-08-2626592494
2026-09-0226652497
2026-09-0326652497

Keep the history. Rebuild the product

TriviaPot was already an existing system when we put the next generation of Descant to work on it. We chose to rebuild in place. Keeping the repository made the old implementation easy to consult: it preserved product history, earlier decisions, and useful references while substantial parts of the system changed around it.

That is a demanding setting for autonomous engineering. Every change has neighbors. A new implementation must fit the surrounding application, and the code that remains can reveal follow-up work as the product evolves. Over weeks, the effort extended through the game, the mobile experience, support, release work, and the operations around the product. On September 3, the public website was updated to point to TriviaPot's live App Store listing.

Convergence, then a deliberate new direction

The first wave of work grew quickly as Descant decomposed the rebuild and captured discoveries as follow-up issues. Creation initially outpaced completion. Then the balance shifted: the backlog narrowed as the implementation converged. By the beginning of July, TriviaPot was working well, with the core feature set in place.

We then chose a new direction: a full visual overhaul and the removal of real-money features for the free-to-play release. That deliberate expansion of scope drove the next rise in issues in early July. Descant carried the redesign across the application, then worked through the visual refinements and follow-ups. The numbered chart annotations show that progression from an expanding plan to a working product and onward into the next development phase.

A codebase that improves with each change

Focused pull requests helped keep a large transformation tractable. Each change could be reviewed in context. Related discoveries could be captured without turning the current patch into an open-ended rewrite. Over time, that discipline changed the whole codebase: new capabilities arrived, existing foundations improved, and the work around launch was completed alongside the application.

This is the kind of sustained development we are building Descant for. We remain responsible for product direction, architecture, and engineering standards. The R&D version supplies an increasingly capable way to execute that direction across many changes, then brings the lessons back into Descant. TriviaPot is available on the App Store if you want to see the resulting product.

Engineering2 min read

The work you discover while doing the work

Long-horizon engineering depends on turning new understanding into follow-through, without letting every pull request grow without limit.

The plan gets better as the code changes

You know the least about a substantial engineering effort at its beginning. A product goal can be clear while the exact path remains incomplete. Implementation reveals a missing requirement, an assumption in neighboring code, or a dependency that the initial breakdown did not capture. Good engineering uses that information to improve the plan.

For Descant, this makes follow-up work part of the product's core behavior. A discovery needs a durable place to live, enough context to be actionable, and a relationship to the work that uncovered it. The next engineer should be able to understand why it matters without reconstructing a conversation that has already ended.

Keep the current change focused

There is a balance to strike. The current pull request needs to satisfy its scope and meet the repository's standards. A useful discovery outside that scope should become follow-up work with its own priority and review. That keeps a small change understandable while preserving the opportunity to improve the surrounding system.

Our August work strengthened that connection between review, follow-up issues, and the relationships among tasks. The intent is straightforward: finish the change in front of you, preserve what you learned, and make the next piece of work explicit. People retain control over which issues are eligible and what comes first.

How a whole codebase changes

Repeated over weeks, this produces a different development experience. A larger goal becomes focused changes. Those changes uncover additional work. Review improves the implementation, while the discoveries improve the backlog. Each merge leaves more useful context for the next one.

This is the pattern we have been developing through TriviaPot and OH HAI. The payoff is sustained progress across the software lifecycle: features, maintenance, integration edges, and the less visible work that makes a product complete. Descant is designed to carry that effort forward, merge by merge, within the scope a team authorizes.

Open specification2 min read

Issuegraph: a work graph for autonomous engineering

A simple, vendor-agnostic way to make dependencies and ordering understandable inside the issue trackers teams already use.

Issuegraph / live demo

Try it
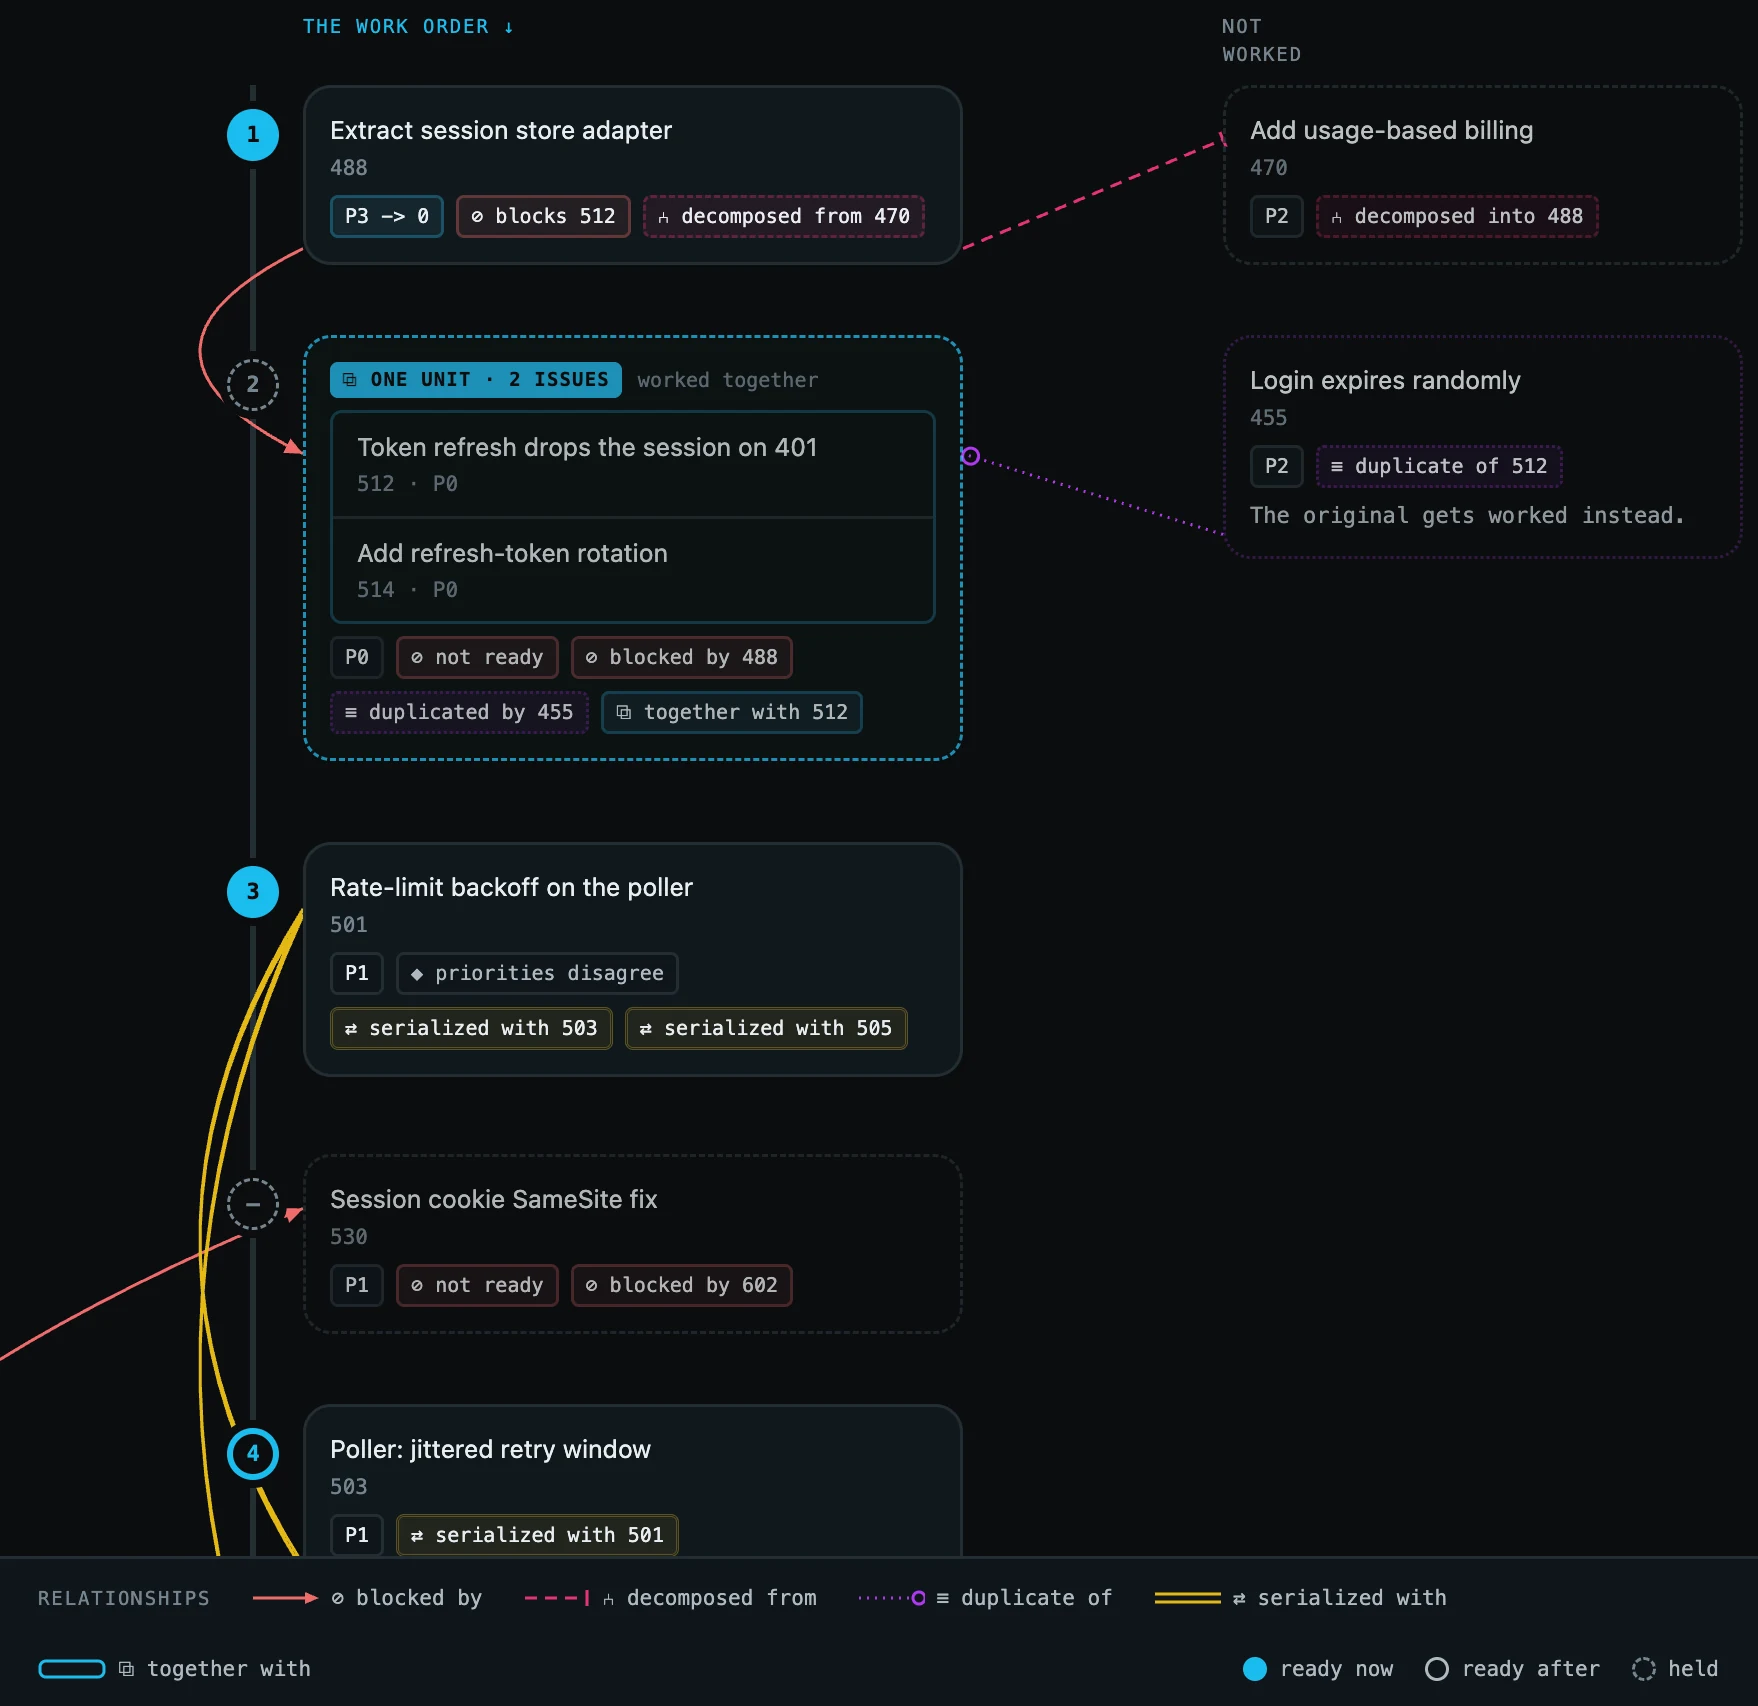
The Issuegraph demo. A numbered work order on the left. Lines connect related issues: one issue blocks the next, two issues are worked together as one unit, three issues are serialized, one was decomposed from a larger issue, and one is a duplicate that is not worked.
A capture of the Issuegraph demo. It orders a sample backlog and draws each relationship that explains the order. Try it in your browser.

A backlog has a shape

A list of issues tells you what exists. Coordinating the work also requires knowing how those issues relate. One change may depend on another. Two tasks may need to happen in sequence. Several smaller issues may come from the same larger goal. As more work happens autonomously, those relationships need a form that software can read consistently.

We created Issuegraph to express that structure inside existing issue trackers. The first public specification took shape on August 14. It gives work relationships a small, explicit, vendor-agnostic format, so the reasoning about what can happen next does not depend on a particular model remembering an earlier conversation.

Keep work where teams already manage it

The useful part is the shared contract. A team can keep its issues, priorities, and discussions in the place it already uses, while tools read the relationships needed to coordinate execution. A larger goal can remain visible as its smaller pieces are filed and completed. Dependencies can be inspected rather than left implicit in a plan.

For Descant, that matters as engineering moves beyond one ticket at a time. Decomposed work needs to retain its ordering. A follow-up needs to connect to the change that revealed it. People need a practical way to see the structure and adjust it. The demo above shows that idea: a work order, and the relationships that explain it.

A foundation other tools can use

Issuegraph is an open specification stewarded by Autonomy. We want the work graph to remain useful across model providers, agent runtimes, and supporting tools. Explicit relationships provide a foundation for coordination even as the systems doing the work change.

The specification and its website are public. If you are building autonomous engineering tools or trying to make a substantial backlog easier for software to understand, take a look. Clear work relationships are a small piece of the overall system, but they support an important goal: consistent progress across many related changes.

Case study5 min read

From protocol to product: building OH HAI with Descant

A coordination problem across hundreds of autonomous agent sessions became an open protocol, then a complete product built with the next generation of Descant.

Many agents. One place to respond

OH HAI began with a problem we were experiencing ourselves.

We routinely run large numbers of autonomous agent sessions across multiple machines and model providers. The agents can work for long periods without supervision. But when an agent needs a decision, that question can become a stopping point inside the session that asked it.

We could come back hours later expecting work to be complete and discover that an agent had spent most of that time waiting for a simple answer.

Checking individual sessions for updates and unanswered questions does not scale. We needed one place where a fleet of agents could reach a person with updates, decisions, and tasks, and where a response could find its way back to the work that needed it.

Many agents. One place to respond
Many agents, one place to respondSix distributed groups of concurrent agent sessions communicate in both directions with OH HAI. One person receives updates, questions, and tasks; decisions and responses route back through OH HAI to the originating work. Stacked cards represent multiple sessions.AgentCAgentOAgentGAgentxAgent>_Agent↔You

Updates · questions · tasks ⇄ decisions · responses

Current account limit: 64 concurrent sessions

Define the protocol before the product

Rather than make that communication model an implementation detail of another application, we started by defining the interface.

That became MA2H: an open protocol for coordination between a person and a fleet of agents across vendors and sessions. The important part was not a particular inbox or runtime. It was establishing a small shared contract that different tools and agents could implement.

The sequence was intentional. Agent systems are changing quickly. Where a useful boundary can be expressed independently of a particular product or vendor, we would rather establish that boundary first and build products against it.

Descant carried that direction into the open specification, supporting implementations, command-line tooling, and reusable skills intended to make MA2H straightforward to add to an agent environment.

Only after that foundation existed did we build OH HAI on top of it.

From protocol to product

OH HAI began differently from TriviaPot.

Before we started building the application, we had already worked through the coordination problem and established the first versions of the MA2H protocol. Once that foundation was clear, we turned to the next question: what product should exist around it?

Working with the R&D version of Descant, we used that protocol and the product direction around it to seed the initial body of work for OH HAI. Descant expanded that starting point into the issues required to build the system, then carried those issues through implementation and review.

That work grew into a web application, service, CLI, hosted MCP interface, session and delivery behavior, agent integrations, and the product surfaces needed to make the whole system coherent.

We set the direction, product requirements, and architectural intent. Descant turned that direction into an implementation plan and carried the resulting work forward. We did not manually write the application code or work through the repository in an editor.

The first time we launched the initial web application, it started without errors. We were immediately able to use it for the first working communication flow based on the MA2H protocol.

That was not the end of development, but it was an unusually clean transition from an operational problem, to an open protocol, to a functioning product built against that protocol.

One product across several interfaces

OH HAI was designed to be agent-native as well as human-facing.

Agents with shell access can use the CLI and maintain a persistent connection. Environments without a shell can communicate through the hosted MCP interface. Other agents can participate through the protocol using the connection model available to their environment. The app and web inbox give the person one place to receive updates, answer questions, and act on tasks.

Those interfaces all meet at the same coordination layer.

A question originating in one environment needs to retain enough identity and context to be answered somewhere else. Sessions can come and go without making the person responsible for monitoring each terminal. Delivery, reachability, identity, and routing have to remain coherent across the system.

That made OH HAI a useful proving ground for Descant: not because any individual component was unusually large, but because a complete product had to emerge across several interfaces and shared contracts.

The human does not have to remain the router

Centralizing agent communication solved the original problem, but it exposed the next bottleneck.

Once enough autonomous work is running, one person can still become overwhelmed simply by being responsible for every question, exception, and operational decision flowing through the inbox.

Because OH HAI is itself agent-native, the coordination layer can also be delegated.

In our own workflow, we sometimes assign an agent to supervise the inbox with explicit authority to triage messages, unblock work, resolve routine CI and merge-queue problems, and make decisions within defined boundaries. That agent effectively acts as a deputy across the larger fleet, escalating the decisions that genuinely require us.

The amount of authority is situational. When Descant is working through large bodies of follow-up work where we care strongly that the work is completed correctly but are less opinionated about each implementation choice, the supervising agent can handle much of the coordination.

When we are actively shaping fundamental behavior in Descant's own pipeline, we keep those decisions close and work the inbox ourselves.

The goal is not to remove the human from the loop. It is to make the loop adjustable: human judgment stays concentrated where it matters, while routine coordination can continue without requiring constant human attention.

A different test of autonomous engineering

TriviaPot and OH HAI exercise almost opposite ends of the problem.

TriviaPot began as a substantial existing system and required sustained transformation across thousands of related changes. OH HAI began with a coordination problem, an open protocol, and a relatively small amount of product direction. Descant then turned that foundation into a working application spanning multiple interfaces.

Both require more than producing isolated code changes.

They require preserving intent while the work expands, discovering what the original plan did not contain, coordinating related changes, and repeatedly bringing those pieces back together into a coherent product.

OH HAI now provides the coordination layer we originally needed for our own autonomous work. Agents can keep working, people can step away, and questions that genuinely require judgment have somewhere durable to go. When appropriate, even the work of supervising that coordination can itself be delegated.

The same process that created that system continues to improve Descant.

Engineering2 min read

Small pull requests. Serious engineering

Focused changes, rigorous review, and architectural intent are the foundations of sustained autonomous development.

Give each change a clear job

Substantial product development becomes easier to reason about when each change has a clear purpose. A focused pull request gives a reviewer a manageable question: does this implementation solve the intended problem, fit the system around it, and meet the engineering standards of the repository? The answer needs to account for more than whether the code was generated successfully.

Descant's workflow is built around that discipline. Planning establishes the intended change. Implementation works within that scope. Review examines the result, and feedback becomes work to resolve. Keeping that loop focused helps a sequence of changes preserve architectural intent as the codebase evolves.

Review belongs inside the development loop

Our July work expanded the review performed before a pull request opens, alongside the separate review that follows it. The goal is to bring more scrutiny into the engineering process: catch problems, address findings, and send a better change into the next stage. Different perspectives are valuable when they produce concrete improvements to the implementation.

Review also needs a sense of scope. A finding about the current change deserves an answer in that change. A separate improvement needs its own piece of work. Preserving that distinction keeps review useful and makes the backlog more informative, without allowing a focused task to expand indefinitely.

The standard has to survive the next hundred changes

Production-grade software depends on choices that compound: clear interfaces, sensible boundaries, maintainable implementations, and an understanding of why the system is shaped the way it is. Those choices have to remain visible as more changes arrive. We are building Descant to carry them forward across the software development lifecycle.

For a team, this should mean substantial work can advance under explicit priorities and merge rules while remaining understandable. Small pull requests are one part of that experience. Their real value is the cumulative result: a product that progresses through changes people can inspect and a codebase that remains a good foundation for the work ahead.

Engineering2 min read

Every merge should make the next one better

Completed work should leave useful knowledge behind, so future changes build on the repository's actual history.

The repository has something to teach

Every completed change contains information that can help the next one. An architectural boundary may become clearer. A local convention may turn out to matter in an unexpected place. A review may explain why an apparently simpler approach would have caused trouble elsewhere. Those lessons are part of the value of doing the work.

A sustained autonomous engineering system needs to carry useful knowledge forward. Descant's July work strengthened the connection between merged changes and the learning process, bringing the actual change and its pull-request context into that work. The aim is practical: future engineering should benefit from what the repository has already taught us.

Preserve decisions that help the next change

Useful learning is specific enough to guide action. It explains the boundary to preserve, the convention to follow, or the reason a decision was made. It should help an engineer approach the next task with better context and fewer repeated discoveries. The codebase and its history remain essential references as the system changes.

This also connects learning to review. A resolved finding can teach more than a correction to one line. It may clarify a pattern that applies across the repository. Carrying that reasoning forward gives the next change a better starting point, while keeping the standards rooted in the actual project.

Progress that compounds

This is central to the Descant we are building. An issue advances through planning, implementation, review, and merge; the result then improves the context for subsequent work. Across many changes, the product develops and the system becomes better informed about the codebase it is maintaining.

We use the next generation of Descant across our own projects to refine that approach under different demands. The lessons improve both the individual repositories and Descant itself. For teams, the ambition is a development system that becomes a more effective collaborator over sustained work, with human direction, architectural intent, and engineering standards carried forward from one change to the next.

Milestone2 min read

Descant's first public benchmark announcement

The starting point: 86.46% on SWE-bench Pro, and an ambition to carry autonomous engineering across sustained product development.

The June 27 announcement

86.46%

SWE-bench Pro

The figure reported in the original announcement. A milestone in the work toward Descant.

A first public signal

On June 27, we shared the first public benchmark announcement for the autonomous software engineering system we were building. The post reported 86.46% on SWE-bench Pro. It also described the pace of our own development: approximately 13,800 GitHub contributions over 60 days, with a previous annual contribution high surpassed in three days.

The result gave us a concrete starting point for talking about Descant. We were building a system that could carry engineering work through a disciplined process and produce changes that stood up to evaluation. The public announcement made that work visible and opened the conversation about what autonomous software engineering could become.

The ambition behind the result

Our main focus is production-grade software engineering over sustained work. A useful system needs to understand the task, make a focused change, respond to review, and preserve the decisions that should guide future changes. It also needs to operate under the authority and standards of the team responsible for the repository.

That is the direction we are taking with Descant: an autonomous engineering system that helps build and evolve whole codebases. The benchmark announcement was an early milestone in that effort. The following months would bring more work on learning, review, work relationships, and the product experience around the engineering loop.

Follow the work from here

This journal brings those milestones together. Some are about how Descant develops a change. Others are about the products we build with its next generation and the lessons that flow back into it. Together they trace the path from a first public result toward a closed beta for teams with meaningful engineering work to delegate.

The original announcement is linked below. It records the 86.46% figure shared on June 27; our October 15 post carries the later published result. As we continue building, we will use this space to show what is changing and what it enables for the people and teams using Descant.